What I Learned Building a RAG Server on my Home Server

Have you ever had an interaction with someone, forgotten whether it was on a thread in slack, on an email, or on a particular whatsapp group, and then not been able to find it? Or know that somewhere you wrote specific instructions for how to add a new screen resolution with xrandr on Linux, but can’t find it (maybe that one’s just me)?

It’s those types of problems that I wanted to solve. So over a few days at the end of October I built a ‘retrieval-augmented generation’ (RAG) server at home, on one box, with no GPU. It now searches 66,398 documents (256,390 passages), from various sources, and answers questions from them with citations.

I’ve kept notes in plain text in git for most of my career. Nearly two thousand files of them, plus a couple of decades of email, plus WhatsApp, Slack workspaces. and LinkedIn messages. grep on my notes and direct searches can find things if I remember the exact word I used at the time, I usually don’t. Even if I can, it’s laborious to manually search in various places. Even remembering where those places could be is onerous and error prone.

Why Build It?

The obvious question is: why not just use one of the many products that do this?

  • Most importantly: the data. The most useful stuff to search is also the most private: Gmail, my WhatsApp, Slack workspaces, LinkedIn messages, private notes, and the transcripts of my Claude Code sessions. I’m not keen on shipping all of that to a third party so it can be indexed for me, even though I basically live on Claude code now.
  • I already had the hardware. The server in my house is a Ryzen 9 7900 (24 threads) with 122 GB of RAM, and no discrete GPU. It already runs Postgres, Ollama, and a bunch of other recently resuscitated projects (thanks to Claude). The marginal cost of another service on it is close to zero.
  • I wanted to understand it. I’d been reading about embeddings, rerankers and ‘hybrid search’ for a while, and I’ve learned over the years that I don’t really understand something until I’ve built it and watched it break. Building it the hard way, in other words.

What It Looks Like
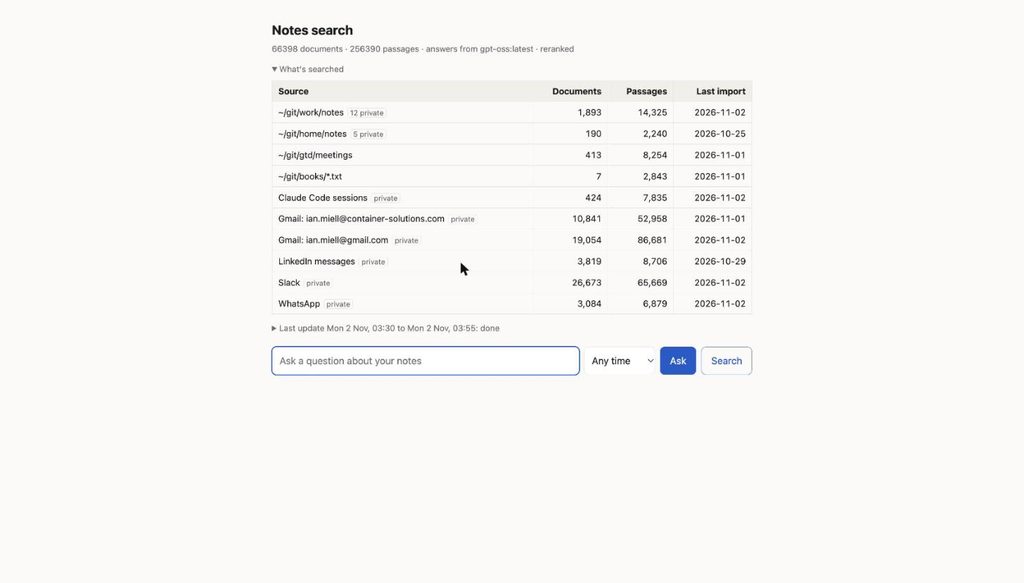
The front page: each source with its documents, passages and last import

Everything tagged ‘private’ gets special treatment, which I’ll come to below.

You type a question and either hit ‘Search’ (just give me the passages) or ‘Ask’ (have a model write an answer from them, with [n] citations). Here’s the xrandr question mentioned above:
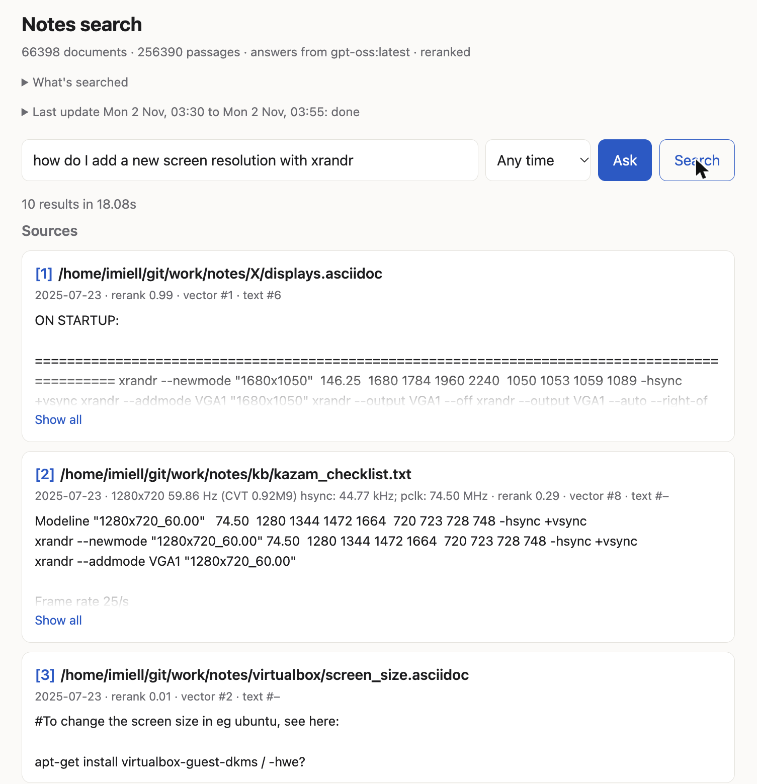
Searching for the xrandr note. The top hit is the right one

The top hit is the right note. Each result shows where it ranked in each of the two searches (‘vector #1 · text #6’) and the reranker’s score (0.99). I left these in the page because they help me see why something did or didn’t come back.

The Stack

Here’s the architecture:
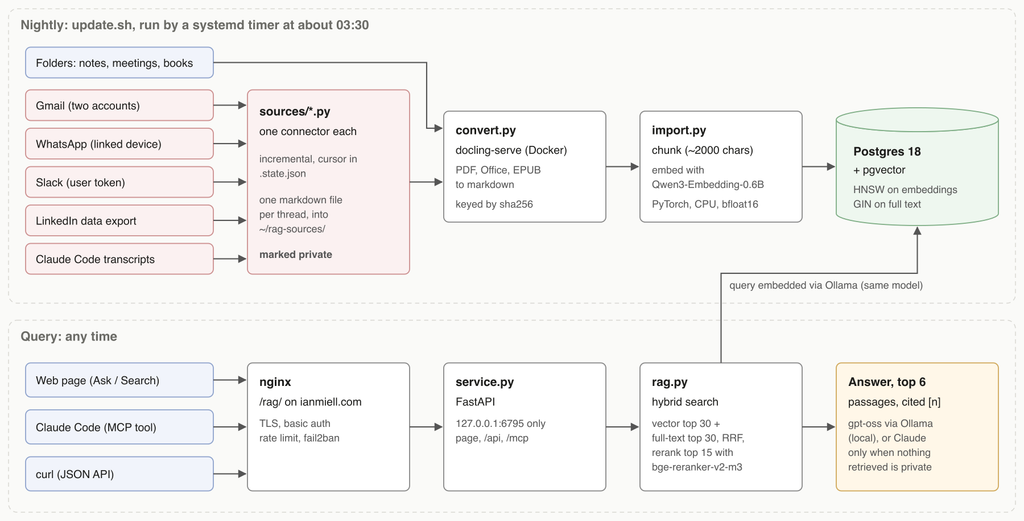
Architecture. Nightly ingest above, queries below.

Going through it from top left:

  • Connectors (sources/*.py): one small script per source. Each fetches only what’s new since last time, keeps its cursor in a .state.json, and writes one markdown file per conversation thread into ~/rag-sources/. Gmail uses the API, WhatsApp uses whatsmeow as a linked device, Slack uses my own user token, and LinkedIn has no messaging API at all, so it parses the data export you can request.
  • Conversion: docling-serve, running in Docker, turns PDFs, Office files and EPUBs into markdown. convert.py keys everything by the file’s SHA-256, so unchanged files are skipped, and a copy of a file in two places is converted once.
  • Chunking and embedding: import.py splits each document on headings into chunks of about 2,000 characters, keeping code blocks whole where it can, and embeds each one with Qwen3-Embedding-0.6B.
  • Storage: Postgres 18 with pgvector. An HNSW index on the embeddings, and a GIN index on a generated tsvector for plain old full-text search. No vector database (I already had Postgres, and I didn’t want another thing to look after).
  • Retrieval (rag.py): the top 30 by vector similarity and the top 30 by full-text search, merged with ‘reciprocal rank fusion’, and then the top 15 reordered by a cross-encoder reranker (bge-reranker-v2-m3).
  • Answers: the top six passages go to gpt-oss running locally in Ollama, or to Claude if nothing in them is private.
  • Interfaces: service.py is a single FastAPI app with the web page, a JSON API and an MCP endpoint, so Claude Code can search my notes as a tool. There’s also search.py for the command line.

A systemd timer runs update.sh every night: connectors, then conversion, then import. This morning’s run took 25 minutes, and the page shows how far it got:
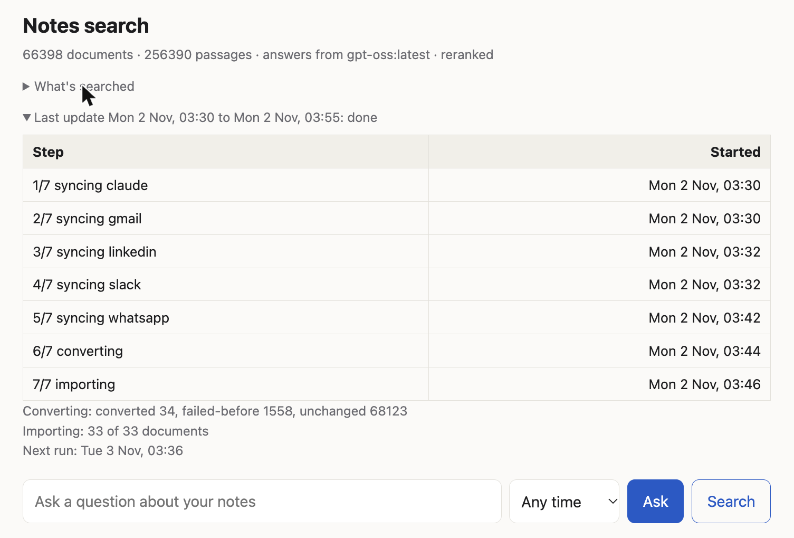
The latest nightly run, step by step

The Python is all uv scripts: each file lists its own dependencies in a comment block at the top, and uv builds the environment the first time you run it. There’s no virtualenv, no requirements.txt, no pyproject.toml. I can’t overstate how much faff that saves on a one-person project.

Lessons Learned

1) Hybrid Search Earns Its Keep

I’d half expected vector search to be enough. It isn’t.

My notes are full of commands, flags, error strings and hostnames. Embeddings are good at ‘what does this mean’ and surprisingly bad at ‘find me this exact token’. Full-text search is the opposite. In the xrandr example above the right note was #1 in the vector search but only #6 in full text, and the second-best result didn’t show up in the full-text list at all. On other queries (an error message, a person’s name) it’s the other way round.

Merging the two ranked lists is a few lines of SQL and Python. If you’re building one of these, do both from day one.

2) The Reranker Is the Slow Part, and Worth It

A search on its own takes about 0.6 seconds. The reranker adds around 15 seconds on a busy box (the search above took 18). That’s a lot, and I can turn it off with RAG_RERANK=0.

I leave it on. The difference in the top three results is big enough that waiting is better than scrolling.

3) On a CPU, How You Run the Model Matters More Than Which Model

I started by embedding through Ollama, since it was already there. It was going to take days.

Running the same model directly in PyTorch, in bfloat16 on 12 threads, was about nine times faster: roughly 2-3 chunks a second. Still not quick (the full notes were about 76,000 chunks, so the first import took hours), but tolerable for an overnight job.

There’s a gotcha hiding in that, though. Queries are still embedded through Ollama (it’s already loaded and it’s fast for one sentence), while documents are embedded in PyTorch. They have to be the same model, or the vectors are meaningless against each other. That’s now written in big letters in the repo’s notes for future me (and for the coding agents).

4) Decide What Not to Index

My first conversion produced about 76,000 chunks of data. Thirty-three vendor-manual PDFs accounted for about 35,000 of them, and other useless old CSVs another 16,800.

All of that is noise. CSVs chunk into meaningless fragments of numbers, and the manuals are public, online and big enough to crowd my own notes out of the results. So there’s an exclude.txt of glob patterns, grouped into tiers, with chunk counts against each so I could see what I was trading off.

Similarly, the Gmail connector only takes threads with people I’ve actually replied or written to. That one rule throws away the newsletters, receipts and spam without me having to write a single filter.

5) Build for the Rerun

Everything is incremental and resumable. Conversion is keyed by content hash and records failures in a sidecar file (there are 1,558 of them, mostly files docling can’t handle, which it skips until I ask it to retry). The import commits each document on its own. The Gmail and Slack connectors checkpoint every minute, so a first sync of a big mailbox that falls over halfway resumes rather than starts again.

A run with nothing new takes a few seconds.

6) Alert on Failure

Similarly, alert.py emails me when a run fails, and also when a source has quietly stopped: no WhatsApp messages for three days (the phone has probably unlinked the bridge), a Slack workspace that hasn’t synced (usually a revoked token), or a LinkedIn export over a month old. Silent staleness is the failure mode of anything that runs at 3am.

7) Dates Are Harder Than They Look

I wanted to ask ‘what was I doing last month?’. That needs a date for each document, and the obvious one, the file’s modification time, is often useless. My notes folder was copied in bulk on 23 July 2025, so as far as the filesystem is concerned every note I’ve ever written dates from that afternoon (which you can see in the search screenshot above).

Messages are better: the connectors write the first and last message dates into the markdown front matter, and an email attachment takes its thread’s dates. Everything else gets the file time, with that caveat.

8) The APIs Have Opinions

Each connector taught me something about the vendor:

  • Gmail: to use the API with OAuth, Google’s consent screen wants links to a home page, a privacy policy and terms of service. For an app with exactly one user. So there are now three static pages on my website explaining, very formally, that I won’t sell my own data to myself.
  • Slack: an app you distribute is limited to one history request a minute. An internal, undistributed app gets about 50.
  • WhatsApp: there’s no official API for your own account, so the bridge is unofficial and acts as a linked device. There’s a small risk WhatsApp objects. If it doesn’t connect for about two weeks the phone unlinks it, hence the alert.
  • LinkedIn: no API at all. You request a copy of your data, wait a day or so, and drop the zip in a folder.

Security

Here’s what’s between the internet and the data:
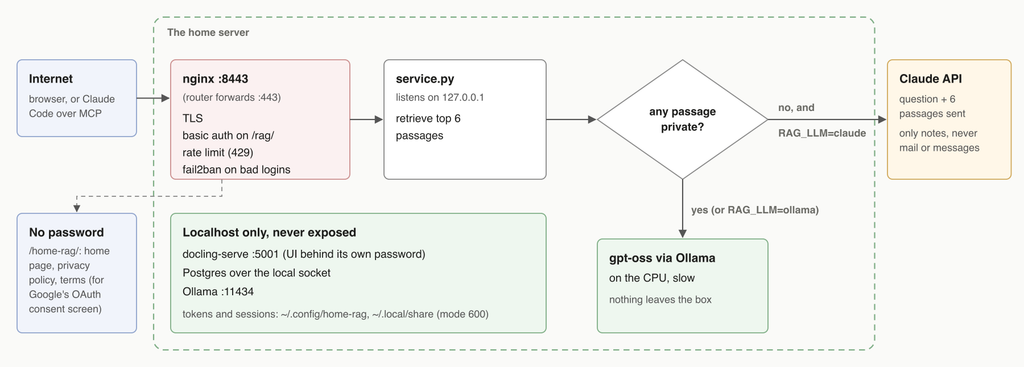
The request path, and where private data may and may not go.

  • One door. The service listens on 127.0.0.1 only. The only way in from outside is nginx, which terminates TLS, asks for a password on /rag/, rate-limits requests and has a fail2ban jail for repeated bad logins. docling, Postgres and Ollama are all on localhost and never exposed.
  • Secrets stay out of the repo. OAuth tokens, the Slack token and the WhatsApp session live under ~/.config/home-rag and ~/.local/share/home-rag, mode 600. The converted text is gitignored. The Claude Code connector replaces anything that looks like a token with [REDACTED] before it’s indexed.
  • Private data is answered locally. Anything from the connectors (mail, messages, transcripts) is flagged private in the database, as is any note with private: true in its front matter. If any of the six passages retrieved for a question is private, the answer comes from the local model, even when the service is configured to use Claude. Claude only ever sees questions answered entirely from my non-private notes, and when it does, it gets the question and those six passages, nothing else.
  • The status page shows counts, not names. The ‘last update’ panel reads the systemd journal, which lists every file converted. The page only shows step names and totals.

Was It Worth It?

In addition to being able to find stuff I wouldn’t have been able to find before, I’ve found that collating all this information has had a few secondary benefits already.

One of the things I like to do is look back on what I’ve done over the last month/quarter/year as a kind of review process. Having this data in one place makes it trivial, as I can just interrogate the data, summarise it and pass it through a local model. It takes a while, but the task can be done asynchronously. As time goes on I am sure I will find more use cases for it.

I’m curious whether other people are doing similar things, and if so, how they differ. Let me know!

If you feel this was useful, consider buying me a coffee to say thanks!
Finding Out What You Actually Liked

When I went up to university I had a worry I didn’t tell anyone about: would I actually enjoy the work?

Up to then I’d always been at or near the top of the class. I suspected a lot of the pleasure I took in school came from that, rather than from the subjects themselves.

The trouble was that university was going to be full of people who’d also been at or near the top of their class. Would I enjoy the work if I was not longer able to distinguish myself through it?

I turned up, and studied hard. I was… average. Not terrible, just somewhere around mediocre.

What surprised me was that I still enjoyed it. A lot.

Being average took away the bit I’d assumed was the point (coming top), and what was left underneath was the reading and the arguing. That turned out to be enough of what I actually liked to keep my motivation.

This got me thinking about what’s happening to software engineers right now.

For a long time, being good at this job meant, in large part, being good at producing code: knowing the syntax, remembering the flags, being able to knock up in ten minutes a script that would take someone else an afternoon. That was the bit you could be top of the class at.

AI is taking that section away. Not all of it, and not perfectly, but enough that ‘can write the code quickly’ isn’t much of a distinction any more. One-shotting a working site is old hat. In other words, we’re all average at that now, or at least as good as whatever model we’re pointing at the problem.

If your sense of yourself was built on being the one who could churn out the code, it might seem like that’s going to hurt. It’s the first term at university all over again.

But strip that section out and you might find out what you liked all along: understanding the system underneath, working out why the business wanted the thing in the first place, and learning something new every week. Some people will discover they really did just like the typing, but fewer than we might think right now.

It took me a whole degree to find out what I actually liked. AI is going to tell a lot of people faster.


If you feel this was useful, consider buying me a coffee to say thanks!

Everything Is An API Now

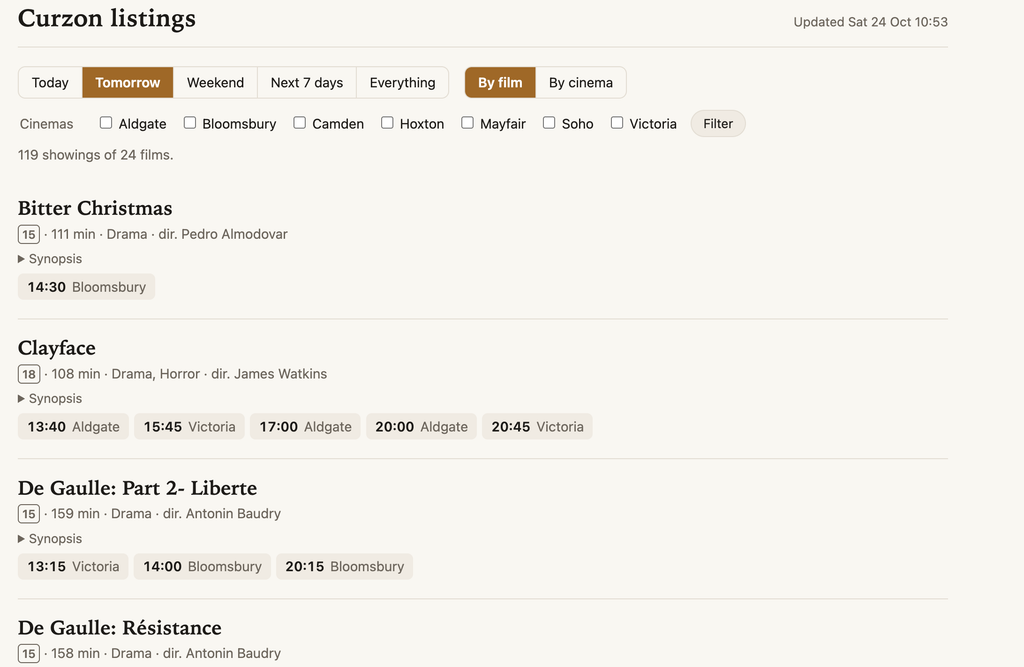
A year ago I used AI to help me build a website that showed cinema listings out of frustration with cinema websites.

(Seriously, what is up with cinema websites? I just want to know what films are on on a given day in cinemas I can reasonably get to. Instead I have to decide either which film I want to see first, or what cinema I want to go to, meaning I have to navigate about 80 pages before I have the information I want. And then I forget what showings I had seen two minutes ago.)

My AI-assisted build was ugly and clunky (it was a hook that triggered a shell script that got the data from the site and put it in a temporary sqlite db, then plain-text output it to the HTTP response – yes, I am that old). But it kinda did the job. After a while it got subject to bit rot, stopped scraping successfully, and I stopped using it and forgot about it.

Tonight I resuscitated it and one-shotted a professional-looking but simple site that still gives me the information I wanted (and more – it added useful stuff like plot synopses and ratings) in 5 minutes. It works perfectly, and I don’t even know what tech it used.

Nothing new in that – one-shotting a useful site now feels old hat now that we’re firing a large chunk of employees because AI.

What it make me think was that everything is an API now.

I don’t need to interact with that annoying cinema site anymore (except to buy tickets, though it’s tempting to automate that as well…). I can just point my harness of choice at it and tell it to give me the interface I prefer.

Everything is an API now. Think of that, and what it means for a software engineer now!


If you feel this was useful, consider buying me a coffee to say thanks!
Reinventing The Wheel, Now At A Bargain Price!

For twenty years, saying “don’t reinvent the wheel” was usually enough to win any argument about writing bespoke software. But that advice assumed two things: writing code was expensive, and importing code was cheap. AI and supply-chain governance are changing both assumptions.


A Short Personal History of Libraries

When I started in software it felt like the wild west in terms of security, audit and compliance. I worked in an unregulated industry as a third party supplier to some FTSE-100 businesses as an engineer. I could tell stories about access and identity management (or the lack of it) that would turn a 2026 CISO’s hair white (or, more likely, whiter).

Wind forward a quarter of a century, and now security is not only its own discipline, but (mostly) fully baked into the software development lifecycle. Compliance is on its way to the party too (this is the area I’m working on at the moment, contact me etc.).

In parallel, software libraries have also become more and more embedded into the software development lifecycle. It may be hard for younger readers to believe, but I spent many years maintaining incredibly busy software platforms that rarely added a publicly available library to its codebase. If we did add them, they were mostly small enough that we could (and usually did) inspect the code ourselves.

These days, it’s not a software project unless you have thousands of npm dependencies you have never even heard of downloaded on an npm install, and my go.mod files can be even longer than the source code for some of my smaller or half-started projects.


The Software Library Pact

Outsourcing engineering to third party libraries always was a trade-off. Writing software was expensive and dangerous. It was far better to outsource bits of that to a freely available online solution. This resulted in a Faustian pact: add all these barely understood dependencies and you won’t need to find the money to finish your project. Aside from the financial benefit, you would get free upgrades, extra functionality you might need in the future, and so on.

This pact was popularised with the slogan ‘do not re-invent the wheel’, which is ancient wisdom to guard against the well-known tendency for engineers to build things unnecessarily to satisfy their creative urges.

However, the consequences of that (perfectly rational) pact are catching up with the industry. Mephistopheles has arrived to take his due, and now engineers’ dependency additions are now continually scanned and analysed for weaknesses by black hat crackers, white hat hackers, supply chain crypto thieves, and auditors alike. When a widely used library has a flaw discovered in it, millions of voices suddenly cry out in terror and are immediately busy managing patches.

It was while talking about these challenges of onerous library management recently with a friend that a thought clarified for both of us that had been circling our consciousness since the advent of LLMs:

Is it now sometimes safer and cheaper to write and maintain bespoke code, rather than importing libraries?

I know this sounds crazy, but let me explain. My friend works in the defence industry. Every new library involves an immense amount of bureaucracy to justify its addition, map its dependencies etc.. Then, once the library is embedded in the codebase, chances are high that flaws will be found in it (or one of its dependencies) that will incur significant bureaucratic costs to upgrade. Think of it like a dependabot workflow, but each alert is a punch in the face.

By contrast, application code that is peculiar to the code requires much less bureaucracy to implement and maintain.

Given that application-specific code is now very significantly cheaper to produce than it has been in the past, and using libraries is now more expensive than it has been in the past, then the calculus behind software delivery has been radically altered. Is it now sometimes safer and cheaper to write and maintain bespoke code, rather than importing libraries? The specific example my friend adduced was a large open source library, a small subset of which’s functionality he wanted to use. He ended up reimplementing that small piece with an LLM, as he reasoned that in that case the various trade-offs were worth it.

I mentioned this notion to an experienced CISO recently and it’s fair to say he was not amenable to the idea. I won’t retail his exact words, as I know some readers have delicate sensibilities.

The CISO objection is not stupid. The industry has learned the hard way that bespoke code is often unreviewed, under-tested, undocumented, and full of boring vulnerabilities. “We wrote it ourselves” is not a security argument.

I’m not giving up on the argument that the calculus has changed though, because I think there’s an economic case to be made in an increasing number of cases. The old mental model was that “npm install is free!”, whereas the new model is that every dependency is a recurring obligation. Each library creates future work: CVE triage, version bumps, breaking changes, SBOM entries, licence checks, audit queries, exception handling, patch windows, and operational risk.


Benefits

Let’s itemize the benefits of choosing to build your own functionality than import dependencies:

1) Writing Code Is Cheaper Than It Was

LLMs can spew out functionality all day, and they’re far, far better at that than maintaining and reasoning about larger systems. You still have to make sure the code it produces works as intended, write tests (LLMs can help with that too), etc., but it’s undeniably cheaper to write an internal library to (for example) prepend characters to a string than it was pre-LLM.

2) It’s Private

Your internal library does not get picked up by code scanners (unless they can comb through your source code directly, in which case they are welcome to find fault). Your internal library does not need to be put in an SBOM. This will reduce noise right across your SDLC.

In other words, bespoke code removes one class of externally visible dependency risk: maintainer compromise, dependency confusion, abandoned packages, and surprise transitive upgrades. It does not remove the need to scan, test, review, and threat-model the code itself.

3) It’s Crafted for Purpose

Code that you make for your needs does exactly what you need it to, and no more.

It’s not subject to any particular library’s bloated attack surface now, or in the future. It doesn’t pick up an increasing number of secondary dependencies over time as it tries to cover more and more features and corner cases you don’t have.

4) It’s Cheaper to Maintain / More Secure

We’ve already discussed some of the ways it can be easier to maintain, but it’s worth itemising the kinds of attacks and disruption that we’ve seen due to third party dependencies:

  • left-pad (2016), where the withdrawal of 11 lines of non-obfuscated code introduced as a library dependency resulted in widespread panic
  • event-stream (2018), where another widely-used package was used as part of a supply chain attack that tried to steal Bitcoin wallets
  • faker.js (2022), where the maintainer decided to ‘upgrade’ his code to a cris de coeur about the ingratitude of the industry towards open source maintainers

The failure modes are not “the library has a bug.” They are: the maintainer disappears, the maintainer is compromised, the maintainer turns hostile, a transitive dependency changes, a package is unpublished, or the ecosystem shifts under you.

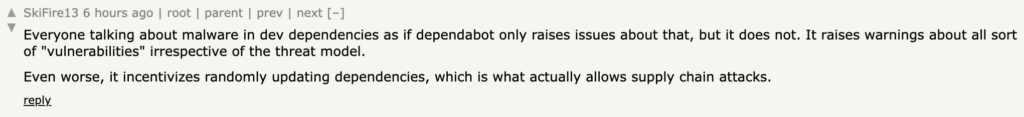
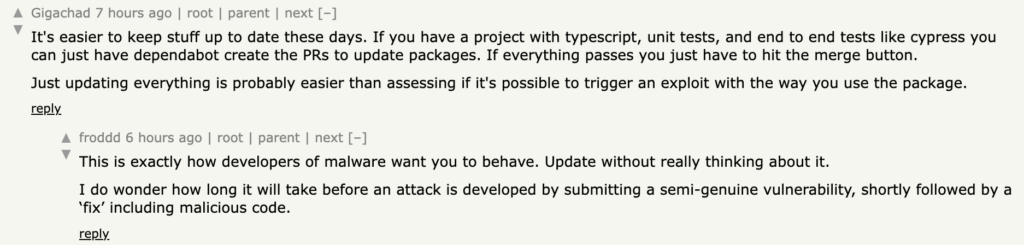
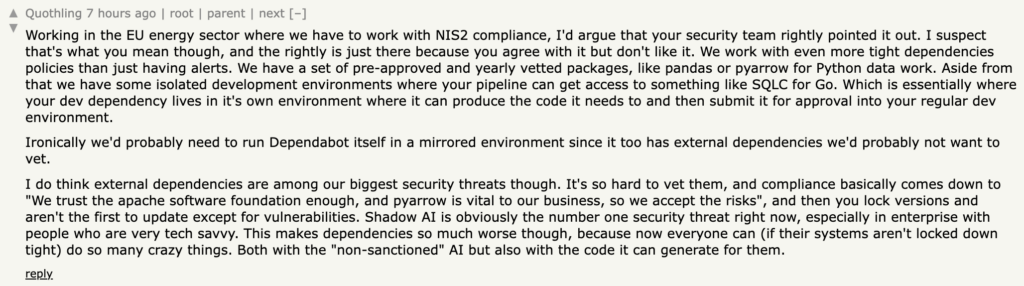
A recent discussion about vulnerability management on HN has some good illustrations of the tensions.

I could also bring in arguments about security through obscurity being a useful (but obviously not sufficient) line of defence, but the itself phrase seems to trigger people, so I won’t.


Objections

The question is not whether we should stop using libraries. The question is whether some dependency imports are now harder to justify than bespoke, narrowly scoped code.

But since what I’m talking about is a trade-off there are of course reasonable objections to raise. I’ll itemise them here, and argue how these arguments’ force has changed recently.

1) It Will Be Less Secure

Your code is specific to you, and hasn’t been subject to a ‘many eyes make bugs shallow’ process of open source delivery. Your code might have old-fashioned flaws like unchecked input, for example.

These objections are self-evidently true. However:

  • LLMs (and other modern tooling) can perform a lot of the security checking of code locally, and far more cheaply than a traditional sec team.
  • Libraries (as we’ve seen above) have attack vectors that make them less secure also.

2) It Will Be Harder to Maintain

I don’t think that will always be true now that we have some form of intelligence to scour our code. Further evidence for how it is hard to maintain libraries is outlined above.

If your code talks to a well-known API for example), then you could argue that using a public library will make you more future proof. Whether that argument holds will depend on how often and significantly the API changes, how much of the API you need to interact with, and how likely it is that the library will be well-maintained in future. I’ve spent a fair amount of time in the last 10 years chasing down poorly maintained libraries that haven’t kept pace with their target API, resulting in me spending significant effort replacing one library with another (or even, not infrequently, having to patch the library with some code I write myself as no such library now exists).

3) If Your Engineers (Now Or In The Future) Are Clueless, This Could Be A Disaster for You

Absolutely.

4) Some Libraries Are Too Important To Rewrite Yourself

Yup. I definitely don’t recommend rolling your own cryptographic libraries, or implementing your own timezone management functionality.

LLMs do not make writing hard software easy. It makes some boring ‘already solved’ software cheap enough that importing a dependency is no longer obviously the cheapest option.


Towards a Decision Framework

Here I propose a quick checklist of things to consider when deciding which way to go. You might want to score each one and to see which way you want to go.

Points for the library:

  • The domain is security-sensitive, complicated or difficult to correctly code
  • The library is mature and widely reviewed
  • The library is well-supported and likely to be maintained for a long time
  • The library has few transitive dependencies (and those dependencies are themselves solid projects)

Consider writing your own when:

  • You only need a small subset of a large library
  • The libraries’ used functions are simple and easily specified
  • The dependency brings many transitive dependencies
  • Approval and vulnerability-management costs are high
  • The code can be exhaustively tested by code you can maintain
  • The blast radius is low

If you feel this was useful, consider buying me a coffee to say thanks!
Fine-Tuning an AI – Part I

This post (Part I) walks you through a Git repo I put together to allow anyone to fine-tune a model to write emails in their own ‘voice’.

I did this to use a small model that I could run at home to help me draft emails that didn’t suck.

You don’t need a hefty GPU, but you will need a credit card to rent one on vast.ai for the training (note: affiliate link – I will benefit if you sign up and spend). It costs me about $1 per run to create a useful model that I can use on my home (non-GPU) server.

Part II will dive deeper into how the script works and what’s going on.

What It Does

At the very highest level, the script creates a new large language model (LLM), building from a base model, and training on sample emails you give it. Here’s some sample output (truncated to 40 tokens):

INPUT:
Write an email to a friend arranging a drink:
OUTPUT:
Hey, how are you? I was thinking of going out for a drink this evening. Are you free? Let me know what time and where we could meet.
Ian
On 10 Jul

You can see how it’s put my name (Ian) at the bottom and a (spurious) date, because that’s why a typical email looks like from me.

Compare this to the ‘base’ model this was built from (Qwen/Qwen2.5-3B-Instruct), which gives a far more ‘generic’ and formal response (also truncated to 40 tokens):

INPUT:
Write an email to a friend arranging a drink:
OUTPUT:
The date is 10/24/10 at 6:00pm.
Subject: Exciting Plans for Our Drink Date!

Dear [Friend's Name],

I hope

That, by contrast, does not sound like me at all.

…in a bit more detail

Here’s what the script (run_fine_tune.sh) does:

  • Picks the cheapest available GPU from vast.ai that fits the criteria needed, and provisions it
  • Copies up a script to run on the machine (build_and_push_model.sh), the gmail samples you want to train it on (compressed), and a huggingface token (to store the resulting models)
  • Runs build_and_push_model.sh on the GPU, which:
    • Installs the needed software (LLaMA-Factory, llama.cpp)
    • Logs into huggingface
    • Creates the huggingface repos (if needed)
    • Trains the new model
    • Merges the new model
    • Converts the new model to .gguf format (allowing it to be run in llama.cpp)
    • Quantizes the new model (so it can be run more easily on a non-GPU machine)
    • Pushes the merged model, and the .gguf, to huggingface repos
  • Destroys the vast.ai instance (asking you first)

How To Run It

The latest instructions will be maintained here:

  1. Clone the repo, and navigate to root folder
  2. Set up the virtual environment, install required pips
  3. Use Google Takeout to download your sent email to a .mbox file. You probably only need your ‘Sent’ emails, as they contain your responses. If you don’t use gmail, the script expects a .mbox file. Then run the python script to extract the emails and put them in the correct format. Then compress the result with xz
  4. Get a huggingface write token
  5. Set up vast.ai api key
  6. Run the script
    • Here’s an example invocation, with placeholders in caps:

./run_fine_tune.sh --max-steps 1 --hf-repo qwen2.5-3b-YOUR_NAME_sft --hf-user YOUR_HUGGING_FACE_ACCOUNT


If you like this, you might like one of my books:
Learn Bash the Hard Way

Learn Git the Hard Way
Learn Terraform the Hard Way


If you feel this was useful, consider buying me a coffee to say thanks!
I’m Writing a New Book!

I’m excited to announce that I’m writing a new book for O’Reilly:

Follow the Money: Understanding the Financial Architecture of Software.

This is a project that’s been quietly brewing for several years. 👇

The book’s primary goal is to help those engineers and managers whose efforts to change their organisations with technology hit the buffers as they scale. The direct application of sweat and resultant problem-solving worked well when you’re a more junior engineer, but as you try to make more fundamental and wide-ranging change seems to work less and less effectively. This book is intended to cast light on the invisible barriers that block your progress, and give you the tools to understand how to change them.

Its secondary goal is to be a more practical guide to making change within technical organisations, and even across wider businesses. While many books and blog posts exist on what the ideal state of various aspects of your organisation (culture, team structure, test practices, platform technologies etc) not enough of them give practical advice on how to get there, which is a far messier process. It might even help your career by allowing you to see how why – and just how challenging – it will be to get there, and perhaps consider setting yourself up for success elsewhere.

I hope the book will distil the experiences I’ve had over the past five years as a Could Native consultant with Container Solutions, and the last 30 years as an engineer, to give the reader a head start in navigating these murky waters.

The book will be replete with practical advice and real-world case studies to illustrate and provide inspiration (and caution) about what lies ahead for those that want to make positive change.

I hope you’ll join me on this journey. If these themes resonate, stay tuned. I’ll be sharing updates, excerpts, and insights here along the way. In the meantime, this video (‘How Money Flows Trump Conway’s Law) shares some of my more embryonic thoughts from a couple of years ago.

Your thoughts, questions, and experiences are always welcome!

Let’s follow the money together.