What I Learned Building a RAG Server on my Home Server

Have you ever had an interaction with someone, forgotten whether it was on a thread in slack, on an email, or on a particular whatsapp group, and then not been able to find it? Or know that somewhere you wrote specific instructions for how to add a new screen resolution with xrandr on Linux, but can’t find it (maybe that one’s just me)?

It’s those types of problems that I wanted to solve. So over a few days at the end of October I built a ‘retrieval-augmented generation’ (RAG) server at home, on one box, with no GPU. It now searches 66,398 documents (256,390 passages), from various sources, and answers questions from them with citations.

I’ve kept notes in plain text in git for most of my career. Nearly two thousand files of them, plus a couple of decades of email, plus WhatsApp, Slack workspaces. and LinkedIn messages. grep on my notes and direct searches can find things if I remember the exact word I used at the time, I usually don’t. Even if I can, it’s laborious to manually search in various places. Even remembering where those places could be is onerous and error prone.

Why Build It?

The obvious question is: why not just use one of the many products that do this?

  • Most importantly: the data. The most useful stuff to search is also the most private: Gmail, my WhatsApp, Slack workspaces, LinkedIn messages, private notes, and the transcripts of my Claude Code sessions. I’m not keen on shipping all of that to a third party so it can be indexed for me, even though I basically live on Claude code now.
  • I already had the hardware. The server in my house is a Ryzen 9 7900 (24 threads) with 122 GB of RAM, and no discrete GPU. It already runs Postgres, Ollama, and a bunch of other recently resuscitated projects (thanks to Claude). The marginal cost of another service on it is close to zero.
  • I wanted to understand it. I’d been reading about embeddings, rerankers and ‘hybrid search’ for a while, and I’ve learned over the years that I don’t really understand something until I’ve built it and watched it break. Building it the hard way, in other words.

What It Looks Like
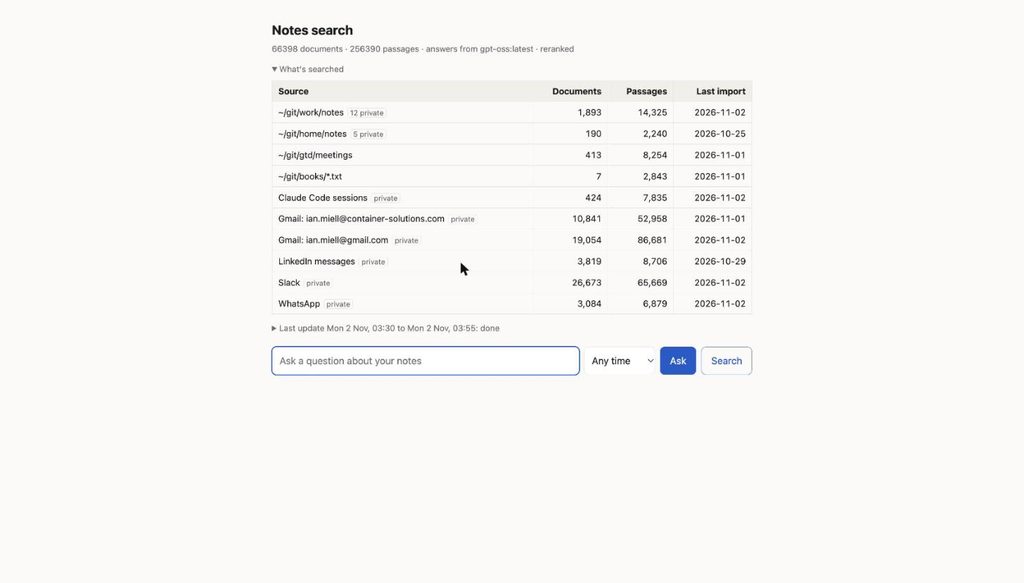
The front page: each source with its documents, passages and last import

Everything tagged ‘private’ gets special treatment, which I’ll come to below.

You type a question and either hit ‘Search’ (just give me the passages) or ‘Ask’ (have a model write an answer from them, with [n] citations). Here’s the xrandr question mentioned above:
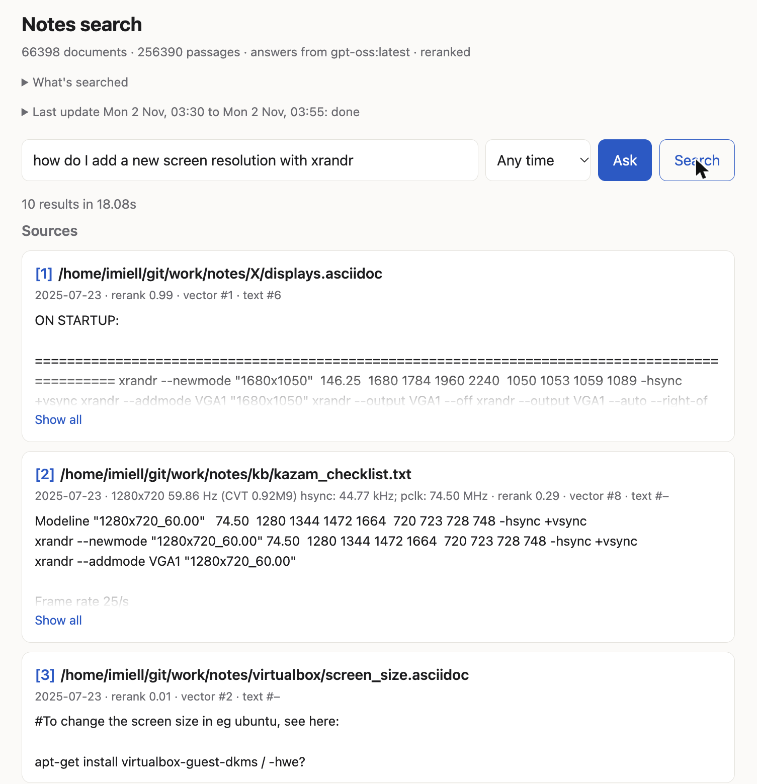
Searching for the xrandr note. The top hit is the right one

The top hit is the right note. Each result shows where it ranked in each of the two searches (‘vector #1 · text #6’) and the reranker’s score (0.99). I left these in the page because they help me see why something did or didn’t come back.

The Stack

Here’s the architecture:
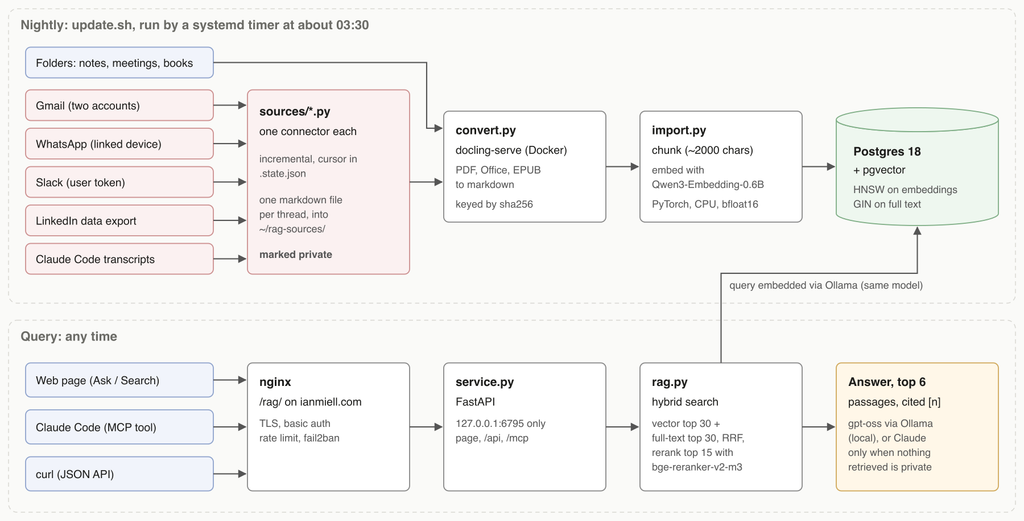
Architecture. Nightly ingest above, queries below.

Going through it from top left:

  • Connectors (sources/*.py): one small script per source. Each fetches only what’s new since last time, keeps its cursor in a .state.json, and writes one markdown file per conversation thread into ~/rag-sources/. Gmail uses the API, WhatsApp uses whatsmeow as a linked device, Slack uses my own user token, and LinkedIn has no messaging API at all, so it parses the data export you can request.
  • Conversion: docling-serve, running in Docker, turns PDFs, Office files and EPUBs into markdown. convert.py keys everything by the file’s SHA-256, so unchanged files are skipped, and a copy of a file in two places is converted once.
  • Chunking and embedding: import.py splits each document on headings into chunks of about 2,000 characters, keeping code blocks whole where it can, and embeds each one with Qwen3-Embedding-0.6B.
  • Storage: Postgres 18 with pgvector. An HNSW index on the embeddings, and a GIN index on a generated tsvector for plain old full-text search. No vector database (I already had Postgres, and I didn’t want another thing to look after).
  • Retrieval (rag.py): the top 30 by vector similarity and the top 30 by full-text search, merged with ‘reciprocal rank fusion’, and then the top 15 reordered by a cross-encoder reranker (bge-reranker-v2-m3).
  • Answers: the top six passages go to gpt-oss running locally in Ollama, or to Claude if nothing in them is private.
  • Interfaces: service.py is a single FastAPI app with the web page, a JSON API and an MCP endpoint, so Claude Code can search my notes as a tool. There’s also search.py for the command line.

A systemd timer runs update.sh every night: connectors, then conversion, then import. This morning’s run took 25 minutes, and the page shows how far it got:
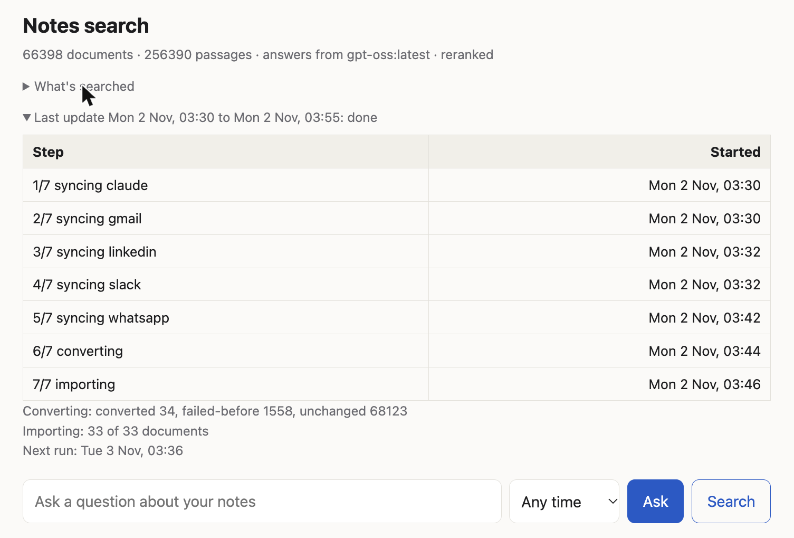
The latest nightly run, step by step

The Python is all uv scripts: each file lists its own dependencies in a comment block at the top, and uv builds the environment the first time you run it. There’s no virtualenv, no requirements.txt, no pyproject.toml. I can’t overstate how much faff that saves on a one-person project.

Lessons Learned

1) Hybrid Search Earns Its Keep

I’d half expected vector search to be enough. It isn’t.

My notes are full of commands, flags, error strings and hostnames. Embeddings are good at ‘what does this mean’ and surprisingly bad at ‘find me this exact token’. Full-text search is the opposite. In the xrandr example above the right note was #1 in the vector search but only #6 in full text, and the second-best result didn’t show up in the full-text list at all. On other queries (an error message, a person’s name) it’s the other way round.

Merging the two ranked lists is a few lines of SQL and Python. If you’re building one of these, do both from day one.

2) The Reranker Is the Slow Part, and Worth It

A search on its own takes about 0.6 seconds. The reranker adds around 15 seconds on a busy box (the search above took 18). That’s a lot, and I can turn it off with RAG_RERANK=0.

I leave it on. The difference in the top three results is big enough that waiting is better than scrolling.

3) On a CPU, How You Run the Model Matters More Than Which Model

I started by embedding through Ollama, since it was already there. It was going to take days.

Running the same model directly in PyTorch, in bfloat16 on 12 threads, was about nine times faster: roughly 2-3 chunks a second. Still not quick (the full notes were about 76,000 chunks, so the first import took hours), but tolerable for an overnight job.

There’s a gotcha hiding in that, though. Queries are still embedded through Ollama (it’s already loaded and it’s fast for one sentence), while documents are embedded in PyTorch. They have to be the same model, or the vectors are meaningless against each other. That’s now written in big letters in the repo’s notes for future me (and for the coding agents).

4) Decide What Not to Index

My first conversion produced about 76,000 chunks of data. Thirty-three vendor-manual PDFs accounted for about 35,000 of them, and other useless old CSVs another 16,800.

All of that is noise. CSVs chunk into meaningless fragments of numbers, and the manuals are public, online and big enough to crowd my own notes out of the results. So there’s an exclude.txt of glob patterns, grouped into tiers, with chunk counts against each so I could see what I was trading off.

Similarly, the Gmail connector only takes threads with people I’ve actually replied or written to. That one rule throws away the newsletters, receipts and spam without me having to write a single filter.

5) Build for the Rerun

Everything is incremental and resumable. Conversion is keyed by content hash and records failures in a sidecar file (there are 1,558 of them, mostly files docling can’t handle, which it skips until I ask it to retry). The import commits each document on its own. The Gmail and Slack connectors checkpoint every minute, so a first sync of a big mailbox that falls over halfway resumes rather than starts again.

A run with nothing new takes a few seconds.

6) Alert on Failure

Similarly, alert.py emails me when a run fails, and also when a source has quietly stopped: no WhatsApp messages for three days (the phone has probably unlinked the bridge), a Slack workspace that hasn’t synced (usually a revoked token), or a LinkedIn export over a month old. Silent staleness is the failure mode of anything that runs at 3am.

7) Dates Are Harder Than They Look

I wanted to ask ‘what was I doing last month?’. That needs a date for each document, and the obvious one, the file’s modification time, is often useless. My notes folder was copied in bulk on 23 July 2025, so as far as the filesystem is concerned every note I’ve ever written dates from that afternoon (which you can see in the search screenshot above).

Messages are better: the connectors write the first and last message dates into the markdown front matter, and an email attachment takes its thread’s dates. Everything else gets the file time, with that caveat.

8) The APIs Have Opinions

Each connector taught me something about the vendor:

  • Gmail: to use the API with OAuth, Google’s consent screen wants links to a home page, a privacy policy and terms of service. For an app with exactly one user. So there are now three static pages on my website explaining, very formally, that I won’t sell my own data to myself.
  • Slack: an app you distribute is limited to one history request a minute. An internal, undistributed app gets about 50.
  • WhatsApp: there’s no official API for your own account, so the bridge is unofficial and acts as a linked device. There’s a small risk WhatsApp objects. If it doesn’t connect for about two weeks the phone unlinks it, hence the alert.
  • LinkedIn: no API at all. You request a copy of your data, wait a day or so, and drop the zip in a folder.

Security

Here’s what’s between the internet and the data:
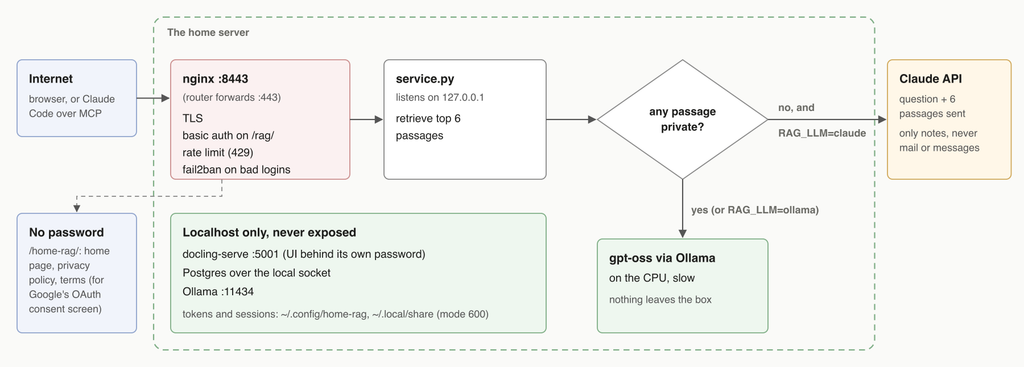
The request path, and where private data may and may not go.

  • One door. The service listens on 127.0.0.1 only. The only way in from outside is nginx, which terminates TLS, asks for a password on /rag/, rate-limits requests and has a fail2ban jail for repeated bad logins. docling, Postgres and Ollama are all on localhost and never exposed.
  • Secrets stay out of the repo. OAuth tokens, the Slack token and the WhatsApp session live under ~/.config/home-rag and ~/.local/share/home-rag, mode 600. The converted text is gitignored. The Claude Code connector replaces anything that looks like a token with [REDACTED] before it’s indexed.
  • Private data is answered locally. Anything from the connectors (mail, messages, transcripts) is flagged private in the database, as is any note with private: true in its front matter. If any of the six passages retrieved for a question is private, the answer comes from the local model, even when the service is configured to use Claude. Claude only ever sees questions answered entirely from my non-private notes, and when it does, it gets the question and those six passages, nothing else.
  • The status page shows counts, not names. The ‘last update’ panel reads the systemd journal, which lists every file converted. The page only shows step names and totals.

Was It Worth It?

In addition to being able to find stuff I wouldn’t have been able to find before, I’ve found that collating all this information has had a few secondary benefits already.

One of the things I like to do is look back on what I’ve done over the last month/quarter/year as a kind of review process. Having this data in one place makes it trivial, as I can just interrogate the data, summarise it and pass it through a local model. It takes a while, but the task can be done asynchronously. As time goes on I am sure I will find more use cases for it.

I’m curious whether other people are doing similar things, and if so, how they differ. Let me know!

If you feel this was useful, consider buying me a coffee to say thanks!
Finding Out What You Actually Liked

When I went up to university I had a worry I didn’t tell anyone about: would I actually enjoy the work?

Up to then I’d always been at or near the top of the class. I suspected a lot of the pleasure I took in school came from that, rather than from the subjects themselves.

The trouble was that university was going to be full of people who’d also been at or near the top of their class. Would I enjoy the work if I was not longer able to distinguish myself through it?

I turned up, and studied hard. I was… average. Not terrible, just somewhere around mediocre.

What surprised me was that I still enjoyed it. A lot.

Being average took away the bit I’d assumed was the point (coming top), and what was left underneath was the reading and the arguing. That turned out to be enough of what I actually liked to keep my motivation.

This got me thinking about what’s happening to software engineers right now.

For a long time, being good at this job meant, in large part, being good at producing code: knowing the syntax, remembering the flags, being able to knock up in ten minutes a script that would take someone else an afternoon. That was the bit you could be top of the class at.

AI is taking that section away. Not all of it, and not perfectly, but enough that ‘can write the code quickly’ isn’t much of a distinction any more. One-shotting a working site is old hat. In other words, we’re all average at that now, or at least as good as whatever model we’re pointing at the problem.

If your sense of yourself was built on being the one who could churn out the code, it might seem like that’s going to hurt. It’s the first term at university all over again.

But strip that section out and you might find out what you liked all along: understanding the system underneath, working out why the business wanted the thing in the first place, and learning something new every week. Some people will discover they really did just like the typing, but fewer than we might think right now.

It took me a whole degree to find out what I actually liked. AI is going to tell a lot of people faster.


If you feel this was useful, consider buying me a coffee to say thanks!

Everything Is An API Now

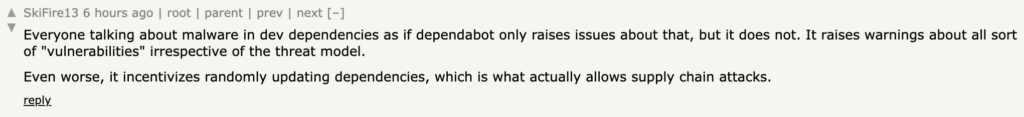
A year ago I used AI to help me build a website that showed cinema listings out of frustration with cinema websites.

(Seriously, what is up with cinema websites? I just want to know what films are on on a given day in cinemas I can reasonably get to. Instead I have to decide either which film I want to see first, or what cinema I want to go to, meaning I have to navigate about 80 pages before I have the information I want. And then I forget what showings I had seen two minutes ago.)

My AI-assisted build was ugly and clunky (it was a hook that triggered a shell script that got the data from the site and put it in a temporary sqlite db, then plain-text output it to the HTTP response – yes, I am that old). But it kinda did the job. After a while it got subject to bit rot, stopped scraping successfully, and I stopped using it and forgot about it.

Tonight I resuscitated it and one-shotted a professional-looking but simple site that still gives me the information I wanted (and more – it added useful stuff like plot synopses and ratings) in 5 minutes. It works perfectly, and I don’t even know what tech it used.

Nothing new in that – one-shotting a useful site now feels old hat now that we’re firing a large chunk of employees because AI.

What it make me think was that everything is an API now.

I don’t need to interact with that annoying cinema site anymore (except to buy tickets, though it’s tempting to automate that as well…). I can just point my harness of choice at it and tell it to give me the interface I prefer.

Everything is an API now. Think of that, and what it means for a software engineer now!


If you feel this was useful, consider buying me a coffee to say thanks!
Reinventing The Wheel, Now At A Bargain Price!

For twenty years, saying “don’t reinvent the wheel” was usually enough to win any argument about writing bespoke software. But that advice assumed two things: writing code was expensive, and importing code was cheap. AI and supply-chain governance are changing both assumptions.


A Short Personal History of Libraries

When I started in software it felt like the wild west in terms of security, audit and compliance. I worked in an unregulated industry as a third party supplier to some FTSE-100 businesses as an engineer. I could tell stories about access and identity management (or the lack of it) that would turn a 2026 CISO’s hair white (or, more likely, whiter).

Wind forward a quarter of a century, and now security is not only its own discipline, but (mostly) fully baked into the software development lifecycle. Compliance is on its way to the party too (this is the area I’m working on at the moment, contact me etc.).

In parallel, software libraries have also become more and more embedded into the software development lifecycle. It may be hard for younger readers to believe, but I spent many years maintaining incredibly busy software platforms that rarely added a publicly available library to its codebase. If we did add them, they were mostly small enough that we could (and usually did) inspect the code ourselves.

These days, it’s not a software project unless you have thousands of npm dependencies you have never even heard of downloaded on an npm install, and my go.mod files can be even longer than the source code for some of my smaller or half-started projects.


The Software Library Pact

Outsourcing engineering to third party libraries always was a trade-off. Writing software was expensive and dangerous. It was far better to outsource bits of that to a freely available online solution. This resulted in a Faustian pact: add all these barely understood dependencies and you won’t need to find the money to finish your project. Aside from the financial benefit, you would get free upgrades, extra functionality you might need in the future, and so on.

This pact was popularised with the slogan ‘do not re-invent the wheel’, which is ancient wisdom to guard against the well-known tendency for engineers to build things unnecessarily to satisfy their creative urges.

However, the consequences of that (perfectly rational) pact are catching up with the industry. Mephistopheles has arrived to take his due, and now engineers’ dependency additions are now continually scanned and analysed for weaknesses by black hat crackers, white hat hackers, supply chain crypto thieves, and auditors alike. When a widely used library has a flaw discovered in it, millions of voices suddenly cry out in terror and are immediately busy managing patches.

It was while talking about these challenges of onerous library management recently with a friend that a thought clarified for both of us that had been circling our consciousness since the advent of LLMs:

Is it now sometimes safer and cheaper to write and maintain bespoke code, rather than importing libraries?

I know this sounds crazy, but let me explain. My friend works in the defence industry. Every new library involves an immense amount of bureaucracy to justify its addition, map its dependencies etc.. Then, once the library is embedded in the codebase, chances are high that flaws will be found in it (or one of its dependencies) that will incur significant bureaucratic costs to upgrade. Think of it like a dependabot workflow, but each alert is a punch in the face.

By contrast, application code that is peculiar to the code requires much less bureaucracy to implement and maintain.

Given that application-specific code is now very significantly cheaper to produce than it has been in the past, and using libraries is now more expensive than it has been in the past, then the calculus behind software delivery has been radically altered. Is it now sometimes safer and cheaper to write and maintain bespoke code, rather than importing libraries? The specific example my friend adduced was a large open source library, a small subset of which’s functionality he wanted to use. He ended up reimplementing that small piece with an LLM, as he reasoned that in that case the various trade-offs were worth it.

I mentioned this notion to an experienced CISO recently and it’s fair to say he was not amenable to the idea. I won’t retail his exact words, as I know some readers have delicate sensibilities.

The CISO objection is not stupid. The industry has learned the hard way that bespoke code is often unreviewed, under-tested, undocumented, and full of boring vulnerabilities. “We wrote it ourselves” is not a security argument.

I’m not giving up on the argument that the calculus has changed though, because I think there’s an economic case to be made in an increasing number of cases. The old mental model was that “npm install is free!”, whereas the new model is that every dependency is a recurring obligation. Each library creates future work: CVE triage, version bumps, breaking changes, SBOM entries, licence checks, audit queries, exception handling, patch windows, and operational risk.


Benefits

Let’s itemize the benefits of choosing to build your own functionality than import dependencies:

1) Writing Code Is Cheaper Than It Was

LLMs can spew out functionality all day, and they’re far, far better at that than maintaining and reasoning about larger systems. You still have to make sure the code it produces works as intended, write tests (LLMs can help with that too), etc., but it’s undeniably cheaper to write an internal library to (for example) prepend characters to a string than it was pre-LLM.

2) It’s Private

Your internal library does not get picked up by code scanners (unless they can comb through your source code directly, in which case they are welcome to find fault). Your internal library does not need to be put in an SBOM. This will reduce noise right across your SDLC.

In other words, bespoke code removes one class of externally visible dependency risk: maintainer compromise, dependency confusion, abandoned packages, and surprise transitive upgrades. It does not remove the need to scan, test, review, and threat-model the code itself.

3) It’s Crafted for Purpose

Code that you make for your needs does exactly what you need it to, and no more.

It’s not subject to any particular library’s bloated attack surface now, or in the future. It doesn’t pick up an increasing number of secondary dependencies over time as it tries to cover more and more features and corner cases you don’t have.

4) It’s Cheaper to Maintain / More Secure

We’ve already discussed some of the ways it can be easier to maintain, but it’s worth itemising the kinds of attacks and disruption that we’ve seen due to third party dependencies:

  • left-pad (2016), where the withdrawal of 11 lines of non-obfuscated code introduced as a library dependency resulted in widespread panic
  • event-stream (2018), where another widely-used package was used as part of a supply chain attack that tried to steal Bitcoin wallets
  • faker.js (2022), where the maintainer decided to ‘upgrade’ his code to a cris de coeur about the ingratitude of the industry towards open source maintainers

The failure modes are not “the library has a bug.” They are: the maintainer disappears, the maintainer is compromised, the maintainer turns hostile, a transitive dependency changes, a package is unpublished, or the ecosystem shifts under you.

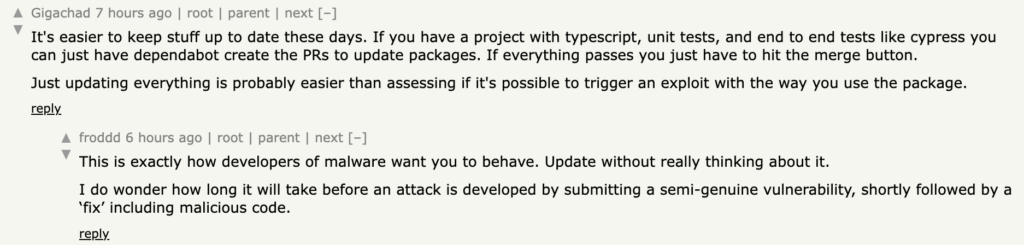
A recent discussion about vulnerability management on HN has some good illustrations of the tensions.

I could also bring in arguments about security through obscurity being a useful (but obviously not sufficient) line of defence, but the itself phrase seems to trigger people, so I won’t.


Objections

The question is not whether we should stop using libraries. The question is whether some dependency imports are now harder to justify than bespoke, narrowly scoped code.

But since what I’m talking about is a trade-off there are of course reasonable objections to raise. I’ll itemise them here, and argue how these arguments’ force has changed recently.

1) It Will Be Less Secure

Your code is specific to you, and hasn’t been subject to a ‘many eyes make bugs shallow’ process of open source delivery. Your code might have old-fashioned flaws like unchecked input, for example.

These objections are self-evidently true. However:

  • LLMs (and other modern tooling) can perform a lot of the security checking of code locally, and far more cheaply than a traditional sec team.
  • Libraries (as we’ve seen above) have attack vectors that make them less secure also.

2) It Will Be Harder to Maintain

I don’t think that will always be true now that we have some form of intelligence to scour our code. Further evidence for how it is hard to maintain libraries is outlined above.

If your code talks to a well-known API for example), then you could argue that using a public library will make you more future proof. Whether that argument holds will depend on how often and significantly the API changes, how much of the API you need to interact with, and how likely it is that the library will be well-maintained in future. I’ve spent a fair amount of time in the last 10 years chasing down poorly maintained libraries that haven’t kept pace with their target API, resulting in me spending significant effort replacing one library with another (or even, not infrequently, having to patch the library with some code I write myself as no such library now exists).

3) If Your Engineers (Now Or In The Future) Are Clueless, This Could Be A Disaster for You

Absolutely.

4) Some Libraries Are Too Important To Rewrite Yourself

Yup. I definitely don’t recommend rolling your own cryptographic libraries, or implementing your own timezone management functionality.

LLMs do not make writing hard software easy. It makes some boring ‘already solved’ software cheap enough that importing a dependency is no longer obviously the cheapest option.


Towards a Decision Framework

Here I propose a quick checklist of things to consider when deciding which way to go. You might want to score each one and to see which way you want to go.

Points for the library:

  • The domain is security-sensitive, complicated or difficult to correctly code
  • The library is mature and widely reviewed
  • The library is well-supported and likely to be maintained for a long time
  • The library has few transitive dependencies (and those dependencies are themselves solid projects)

Consider writing your own when:

  • You only need a small subset of a large library
  • The libraries’ used functions are simple and easily specified
  • The dependency brings many transitive dependencies
  • Approval and vulnerability-management costs are high
  • The code can be exhaustively tested by code you can maintain
  • The blast radius is low

If you feel this was useful, consider buying me a coffee to say thanks!
Fine-Tuning an AI – Part I

This post (Part I) walks you through a Git repo I put together to allow anyone to fine-tune a model to write emails in their own ‘voice’.

I did this to use a small model that I could run at home to help me draft emails that didn’t suck.

You don’t need a hefty GPU, but you will need a credit card to rent one on vast.ai for the training (note: affiliate link – I will benefit if you sign up and spend). It costs me about $1 per run to create a useful model that I can use on my home (non-GPU) server.

Part II will dive deeper into how the script works and what’s going on.

What It Does

At the very highest level, the script creates a new large language model (LLM), building from a base model, and training on sample emails you give it. Here’s some sample output (truncated to 40 tokens):

INPUT:
Write an email to a friend arranging a drink:
OUTPUT:
Hey, how are you? I was thinking of going out for a drink this evening. Are you free? Let me know what time and where we could meet.
Ian
On 10 Jul

You can see how it’s put my name (Ian) at the bottom and a (spurious) date, because that’s why a typical email looks like from me.

Compare this to the ‘base’ model this was built from (Qwen/Qwen2.5-3B-Instruct), which gives a far more ‘generic’ and formal response (also truncated to 40 tokens):

INPUT:
Write an email to a friend arranging a drink:
OUTPUT:
The date is 10/24/10 at 6:00pm.
Subject: Exciting Plans for Our Drink Date!

Dear [Friend's Name],

I hope

That, by contrast, does not sound like me at all.

…in a bit more detail

Here’s what the script (run_fine_tune.sh) does:

  • Picks the cheapest available GPU from vast.ai that fits the criteria needed, and provisions it
  • Copies up a script to run on the machine (build_and_push_model.sh), the gmail samples you want to train it on (compressed), and a huggingface token (to store the resulting models)
  • Runs build_and_push_model.sh on the GPU, which:
    • Installs the needed software (LLaMA-Factory, llama.cpp)
    • Logs into huggingface
    • Creates the huggingface repos (if needed)
    • Trains the new model
    • Merges the new model
    • Converts the new model to .gguf format (allowing it to be run in llama.cpp)
    • Quantizes the new model (so it can be run more easily on a non-GPU machine)
    • Pushes the merged model, and the .gguf, to huggingface repos
  • Destroys the vast.ai instance (asking you first)

How To Run It

The latest instructions will be maintained here:

  1. Clone the repo, and navigate to root folder
  2. Set up the virtual environment, install required pips
  3. Use Google Takeout to download your sent email to a .mbox file. You probably only need your ‘Sent’ emails, as they contain your responses. If you don’t use gmail, the script expects a .mbox file. Then run the python script to extract the emails and put them in the correct format. Then compress the result with xz
  4. Get a huggingface write token
  5. Set up vast.ai api key
  6. Run the script
    • Here’s an example invocation, with placeholders in caps:

./run_fine_tune.sh --max-steps 1 --hf-repo qwen2.5-3b-YOUR_NAME_sft --hf-user YOUR_HUGGING_FACE_ACCOUNT


If you like this, you might like one of my books:
Learn Bash the Hard Way

Learn Git the Hard Way
Learn Terraform the Hard Way


If you feel this was useful, consider buying me a coffee to say thanks!
I’m Writing a New Book!

I’m excited to announce that I’m writing a new book for O’Reilly:

Follow the Money: Understanding the Financial Architecture of Software.

This is a project that’s been quietly brewing for several years. 👇

The book’s primary goal is to help those engineers and managers whose efforts to change their organisations with technology hit the buffers as they scale. The direct application of sweat and resultant problem-solving worked well when you’re a more junior engineer, but as you try to make more fundamental and wide-ranging change seems to work less and less effectively. This book is intended to cast light on the invisible barriers that block your progress, and give you the tools to understand how to change them.

Its secondary goal is to be a more practical guide to making change within technical organisations, and even across wider businesses. While many books and blog posts exist on what the ideal state of various aspects of your organisation (culture, team structure, test practices, platform technologies etc) not enough of them give practical advice on how to get there, which is a far messier process. It might even help your career by allowing you to see how why – and just how challenging – it will be to get there, and perhaps consider setting yourself up for success elsewhere.

I hope the book will distil the experiences I’ve had over the past five years as a Could Native consultant with Container Solutions, and the last 30 years as an engineer, to give the reader a head start in navigating these murky waters.

The book will be replete with practical advice and real-world case studies to illustrate and provide inspiration (and caution) about what lies ahead for those that want to make positive change.

I hope you’ll join me on this journey. If these themes resonate, stay tuned. I’ll be sharing updates, excerpts, and insights here along the way. In the meantime, this video (‘How Money Flows Trump Conway’s Law) shares some of my more embryonic thoughts from a couple of years ago.

Your thoughts, questions, and experiences are always welcome!

Let’s follow the money together.

Exploring OSCAL Using Neo4J

This post is aimed at those interested in continuous compliance, an extension of cloud native principles to the area of software compliance, an under-developed field of software automation.

My consultancy, Container Solutions is working on an open source project to help automate the management and reporting of controls, and this post arose from that work.

OSCAL?

OSCAL stands for “Open Security Controls Assessment Language”.

It’s a standard maintained by NIST. Like many standards, it’s big and full of jargon, difficult for outsiders to grok, and obviously designed by committee, but trying to encompass an area like this across a whole set of industries is hard, and there’s no other game in town.

The OSCAL ‘Schema’

OSCAL was created to be a flexible but complete standard for exchanging information about security controls.

It’s designed to define machine-readable documents that represent different parts of the controls lifecycle, such as assessments, risk identification, and ‘plans of action’. The idea is that participants and software within this lifecycle can exchange information using a common, machine-readable language.

For example, a regulator might publish “Control Catalogs” using OSCAL as a document format. These publications can then be read by software used by various parties involved in compliance to facilitate their work.

To give you an idea, here’s an example, minimal and edited OSCAL document, from the examples repo. It represents an Assessment Plan, one of the phases in the control lifecycle:

OSCAL document example

You can imagine how that document could be read by a desktop application which presents this information in a way that can be used by someone about to perform an assessment of controls. Note that the ‘uuids’ can be referenced by other documents’ entities, and that there are uuids that could refer to other documents’ entities. This will be relevant later.

Other entities modelled by OSCAL include:

  • Catalogs (lists of controls and their details)
  • Profiles (sets of controls derived from catalogs)
  • Implementations (details of how control is applied)
  • Assessment Plans (how the controls will be tested)
  • Assessment Results (findings from the assessment process)
  • Plan of Action and Milestone (corrective actions for addressing findings)

and here is a visual representation from the OSCAL site:

OSCAL Layers and Models Visualisation

The Problem

For someone old like me who is used to a more monolithic and relation-oriented schema, OSCAL feels odd. Different documents at different levels may or may not have elements that relate to one another, and might be completely independent. For example, a control definition that exists in one doc might be referenced in another by a UUID being the same, but there’s no definition of whether such a relation needs to exist or not.

However, both in practice and in the examples given by NIST, the data ‘feels’ relational 

Visualising OSCAL with Neo4J

While working on this, a colleague mentioned this talk from Alexander Koderman, (slides) where he demonstrated how to use Neo4J to visualise OSCAL documents. Along the way he discovered errors in the documents and could relate, isolate, and more easily visualise parts of the documents he was looking at:

https://youtube.com/watch?v=FVCFmSIsYic%3Ffeature%3Doembed

Building on this work, I set up a repo to run up a Neo4J instance in docker, after which I could play with the nodes in an interactive way. This made learning about OSCAL and the relations between the nodes a lot more fun.

Images are available here.

System Security Plan

SSP Visualisation

An OSCAL example System Security Plan (highlighted) and its related nodes. Where possible, size and colour have been used to distinguish different types of node. The type of node can be inferred from the relation described between them in the arrows, but if you click on them, the details can be reviewed.

Catalog

Catalog VisualisationAn OSCAL example catalog (highlighted) and its related nodes.

Assessment Plan and Plan of Action and Milestones

AP and AR VisualisationThis graph shows how the Plan of Action and Milestones (highlighted, large brown node) is related to the Assessment Plan (the large orange node). Tracing through, you can see that ‘Assessment Plan’ nodes are related to ‘Assessment Result’ nodes via ‘Party’ nodes and ‘Role’ nodes.
Code

The code for running this on your own machine on Docker, along with the above images, is available here. Simply clone it and run make full-rebuild and you will see instructions on how to get the same views on the OSCAL examples.


If you like this, you might like one of my books:
Learn Bash the Hard Way

Learn Git the Hard Way
Learn Terraform the Hard Way

LearnGitBashandTerraformtheHardWay
Buy in a bundle here

This post was originally published here, and is re-posted with permission.

Does Crossplane Replace Terraform? Part I: the Theory

What is Crossplane?

If you don’t already know, Crossplane is billed as an:

Open source, CNCF project built on the foundation of Kubernetes to orchestrate anything. Encapsulate policies, permissions, and other guardrails behind a custom API line to enable your customers to self-service without needing to become an infrastructure expert.

Another way to view Crossplane is as a tool that uses a commodity, open source, and well-supported control plane (Kubernetes) to support the creation of other control planes.

We’ve been using it at Container Solutions for a while, and have recently been talking about how we think it’s going to become more important in future:

Recently I’ve been watching Viktor Farcic’s fantastic set of tutorial videos on Crossplane. If you are an engineer or interested architect, then these primers are ideal for finding out what’s going on in this area.

While following Viktor’s work I saw another Crossplane-related video by Viktor on a subject we both seem to get asked about a lot: does Crossplane replace Terraform/Ansible/Chef/$Tool?

https://youtube.com/watch?v=tgwxMfIsLJY%3Ffeature%3Doembed

This is a difficult question to answer briefly (aside from just saying “yes and no”), because understanding the answer requires you to grasp what is new and different about Crossplane, and what is not. It doesn’t help that – from the user point of view – they can seem to do the exact same thing.

To get to the answer, I want to reframe a few things Viktor says in that video that confused me, in the hope that the two pieces of content taken together help people understand where Crossplane fits into the Cloud Native firmament. Although Viktor and I agree on the role Crossplane plays now and in the future, we do differ a little on defining and interpreting what is new about Crossplane, and how the industry got here.

This post follows the logic of our ‘Cloud Native Family Tree’, which seeks to explain the history of devops tooling. It’s recently been updated to include Crossplane.

history_devops_tools.drawio (1)

Three Questions

Before we get into the debate, we may want to ask ourselves two deceptively simple questions:

  • What is an API?
  • What is a cloud service?

And one non-simple question:

  • What is a control plane?

Understanding exactly what the answers to these are is key to defining what’s new and useful about Crossplane.

If you think you know these already, or aren’t interested in the philosophy, skip to the end.

What is an API?

Let’s start with a definition from an AWS page:

APIs are mechanisms that enable two software components to communicate with each other using a set of definitions and protocols.

Nowadays, most people think of an API as a set of services you can call using technologies like HTTP and JSON. But HTTP and JSON (or YAML, or XML etc) are not necessary. In this context, I like to explain to people that the venerable mkdir command is an API. mkdir conforms in these ways:

  • enables two software components to communicate with each other [the shell and the Linux API] using
  • a set of definitions [the standard flags to mkdir] and
  • protocols [shell standard input/output and exit codes]

Pretty much all code is something that calls an API, down to whatever goes on within the hardware (which, by definition, isn’t a software component). Technically speaking, code is “APIs all the way down”. But this isn’t a very helpful definition if it essentially describes all code.

mkdir's calls to the Linux APIAPIs all the way down: The Linux API calls that mkdir makes in order to create a folder.

It might be argued that mkdir is not an API because it is used by humans, and not for ‘two software components to communicate’. However, you can telnet to a server and call its API by hand (I used to do this via HTTP a lot when debugging). Further, mkdir can (and is also designed to) be used within scripts  

APIs are Stable

What people really want and expect from an API is stability. As a rule, the lower down the stack an API is, the more stable it needs to be. The Intel x86 API has had very few breaking changes since it came into being in 1978, and even carries over idiosyncrasies from the Datapoint 2022 terminal in 1970 (such as the 8086’s ‘little endian’ design. Similarly, the Linux Kernel API has also had very few changes (mostly removals) since version 2.6‘s release over 20 years ago (2003).

The Linux CLI, by contrast, is much less stable. This is one of the main reasons shell scripts get such a bad rep. They are notoriously difficult to write in such a way that they can be run on a wide variety of different machines. Who knows if the ifconfig command in my shell script will run in your target shell environment? Even if it’s installed and on the $PATH, and not some other command with the same name, will it have the same flags available? Will those flags do the same thing consistently? Defensively writing code against these challenges are probably the main reason people avoid writing shell scripts, alongside the ease with which you can write frighteningly broken code.

This is why tools like Ansible came into being. They abstracted away the messiness of different implementations of configuration commands, and introduced the notion of idempotence to configuration management. Rather than running a mkdir command which might succeed or fail, in Ansible you simply declare that the folder exists. This code will create a folder on ‘all’ your defined hosts.

- hosts: all
  tasks:
    - name: Create a folder
      file:
        path: /path/to/your/folder
        state: directory

Ansible will ssh into them and create the folder if it doesn’t already exist, running mkdir, or whatever it needs to run to get the Linux API to deliver an equivalent result.

Viktor says that Ansible, Chef et al focussed on ‘anything but APIs’, and this is where I disagree. They did focus on APIs, but not http-based (or ‘modern’) APIs; they simplified the various command line APIs into a form that was idempotent and (mostly) declarative. Just as mkdir creates a new API in front of the Linux API, Ansible created a means to use (or create your own) APIs that simplified the complexity of other APIs. 

Terraform: An Open Plugin and Cloud First Model

Terraform not only simplified the complexity of other APIs, but then added a rich and open plugin framework and a ‘cloud first’ model (as opposed to Ansible’s ‘ssh environment first’ model). In theory, there was no reason that Ansible couldn’t have done the same things Terraform did, but Ansible wasn’t designed for infrastructure provisioning the way Terraform was (as Viktor points out).

This begs the second question: if Terraform was ‘cloud first’…

What is a Cloud Service?

Many people think of a cloud service as something sold by one of the big three hyperscalers. In fact, a cloud service is the combination of three things:

  • A remote network connection
  • An API
  • A delegation of responsibility to a third party

That’s it. That’s all a cloud service is.

We’ve already established that an API (as opposed to just ‘running software’) is a stable way for two software components to communicate. Cloud simply takes this and places it on the network. Finally – and crucially – it devolves responsibility for delivering the result to a third party.

So, if I ask my Linux desktop (y’know, the one literally on my desk) for more memory, and it can’t give it to me because it’s run out, then that’s my responsibility to resolve, therefore it’s not a cloud service.

A colo is not a cloud service, for example, because the interface is not an API over a network. If I want a new server I’ll send them an email. If they add an API they become a cloud service.

This table may help clarify:

 Remote Network ConnectionAPIDelegation of Responsibility
AbacusNoNoNo
Linux ServerYesNoNo
mkdir CLI Command on Desktop LinuxNoYesNo
Outsourced On-Prem ServerNoNoYes
Self-managed API serviceYesYesNo
Windows Operating System on DesktopNoYesYes
Colo ServerYesNoYes
AWS EKSYesYesYes
GitHubYesYesYes
  • An abacus is a simple calculation tool that doesn’t use a network connection, has an interface (moving beads), but not an API, and if the abacus breaks, that’s your problem.
  • A Linux server has a remote network connection, but no API for management. (SSH and the CLI might be considered an API, but it’s certainly not stable).
  • mkdir has an API (see above), but from mkdir‘s point of view, disk space is your problem.
  • If you engage a company to supply you with an on-prem server, then it’s their problem if it breaks down (probably), but you don’t generally have an API to the outsourcer.
  • If you build your own API and manage it yourself then you can’t pick up the phone to get it fixed if it returns an error.
  • If the Windows API breaks (and you paid for support), then you can call on Microsoft support, but the Windows API doesn’t need a network connection to invoke.
  • A colo server is supplied by you without an API, but if it doesn’t get power/bandwidth/whatever else the colo supports, you can get them to fix it, and can connect to it over the network.

Some of these may be arguable on detail, but it’s certainly true that only EKS and GitHub qualify as ‘cloud services’ in the above table, as they fulfil all three criteria for a cloud service.

What is a Control Plane?

A less commonly-understood concept that must also be understood is the ‘control plane’. The phrase comes from network routing, which divides the router architecture into three ‘planes’: the ‘data plane’, the ‘control plane’, and the ‘management plane’.

In networking, the data plane is the part of the software that processes the data requests. By contrast, the control plane is the part of the software that maintains the routing table and defines what to do with incoming packets, and the management plane handles monitoring and configuration of the network stack. 

You might think of the control plane as the state management of the data that goes through the router, as opposed to the general management and configuration of the system (management plane).

This concept has been co-opted by other technologies, but I haven’t been able to find a formal definition of what a control plane when used outside of networking. I think of it as ‘whatever manages how the useful work will be done by the thing’ rather than the thing that does the actual work. If that doesn’t seem like a rigorous definition to you, then I won’t disagree.

For Kubernetes, the control plane is the etcd database and the core controllers that make sure your workloads are appropriately placed and running.

All cloud services need a control plane. They need something that orchestrates the delivery of services to clients. This is because they have a remote API and a delegation of responsibility.

So Does Crossplane Replace Terraform?

OK, now we know what the following things are:

  • APIs
  • Cloud services
  • Control planes

We can more clearly explain how Crossplane and Terraform (et al) relate.

Resources, APIs, Cloud Services

Crossplane and Terraform both deal with the creation of resources, and are both designed to help manage cloud services. In this sense, Crossplane can replace Terraform. However…

‘One-shot’ vs Continuous

…whereas Terraform is ‘one-shot‘ (you run it once and then it’s done), Crossplane is continuous. Part of its job is to provision resources, but it’s not its only job. Its design, and main purpose, is to give you a framework to ensure that resources remain in a ‘known state’, ultimately deriving its source of truth from the configuration of its own Kubernetes control plane (or Git, if this configuration is synchronised with a Git repository).

Terraform ‘Under’ Crossplane?

If you want, you can run your Terraform code in Crossplane with the Terraform provider. One thing to note here, thought, is that you can’t just take your existing Terraform code or other shell scripts and run it unchanged ‘within’ Crossplane’s control plane just as you would have done before. Some work will need to be done to integrate the code to run under Crossplane’s control. In this sense, Crossplane does replace Terraform, subsuming the code into its own provider.

Control Planes

In a way, Crossplane is quite close to Chef and Puppet. Both those tools had ‘control planes’ (the Chef and Puppet servers) that ensured the targets were in a conformant state. However, Chef and Puppet (along with Ansible) were designed to configure individual compute environments (physical servers, VMs etc), and not orchestrate and compose different APIs and resources into another cloud service-like API.


If you like this, you might like one of my books:
Learn Bash the Hard Way

Learn Git the Hard Way
Learn Terraform the Hard Way

LearnGitBashandTerraformtheHardWay
Buy in a bundle here

This post was originally published here, and is re-posted with permission.

In Praise of Low Tech DevEx

When I started my career as an engineer in the early noughties, I was very keen on developer experience (devex).

So when I joined a company whose chosen language was TCL (no, really), I decided to ask the engineering mailing list what IDEs they used. Surely the senior engineers, with all their wisdom and experience, would tell which of the many IDEs available at the time made them the most productive? This was decades before ‘developer experience’ had a name, but nonetheless it was exactly what I was talking about, and what people fretted about.

Minutes later, I received a terse one-word missive from the CTO:

From: CTO
Subject: IDEs

> Which IDEs do people recommend using here? Thanks,
> Ian

vim

Being young and full of precocious wisdom, I ignored this advice for a while. I installed Eclipse (which took up more RAM than my machine had, and quickly crashed it), and settled on Kate (do people still use Kate?). But eventually I twigged that I was no more productive than those around me that used vim.

So, dear reader, I married vim. That marriage is still going strong twenty years later, and our love is deeper than ever.

This pattern has been repeated multiple times with various tools:

  • see the fancy new GUI
  • try it
  • gradually realise that the command-line, text-only, steep-learning-curve, low-tech approach is the most productive

Some time ago it got to the point where when someone shows me the GUI, I ask where the command-line version is, as I’d rather use that. I often get funny looks at both this, and when I say I’d rather not use Visual Studio if possible.

I also find looking at gvim makes me feel a bit queasy, like seeing your dad dancing at a wedding.

This is not a vim vs not-vim post. Vim is just one of the oldest and most enduring examples of an approach which I’ve found has served me better as I’ve got older.

I call this approach ‘low-tech devex’, or ‘LTD’. It prefers:

  • Long-standing, battle-hardened tools that have stood the test of time
  • Tools with stable histories
  • Small tools with relatively few dependencies
  • Text-based input and output
  • Command-line approaches that exemplify unix principles
  • Tools that don’t require daemons/engines to run

LTD also is an abbreviation of ‘limited’, which seems appropriate…

How Is Low-Tech Devex Better?

All LTD tools arguably reflect the aims and principles of the UNIX philosophy, which has been summarised as:

Write programs that do one thing and do it well. Write programs to work together. Write programs to handle text streams, because that is a universal interface.

Portability

LTD is generally very portable. If you can use vim, it will work in a variety of situations, both friendly and hostile. vim, for example can easily be run on Windows, MacOS, Linux, or even that old HPUX server which doesn’t even run bash, yet does run your mission-critical database.

Speed

These tools tend to run fast when doing their work, and take little time to start up. This can make a big difference if you are in a ‘flow’ state when coding. They also tend to offer fewer distractions as you’re working. I just started up VSCode on my M2 Mac in a random folder with one file in it, and it took over 30 seconds until I could start typing.

Power

Although the learning curve can be steep, these tools tend to allow you to do extremely powerful things. The return on the investment, after an initial dip, is steep and long-lasting. Just ask any emacs user.

Composability / Embeddability

Because these tools have fewer dependencies, they tend to be more easily composable with – or embeddable in – one another. This is a consequence of the Unix philosophy.

For example, using vim inside a running Docker container is no problem, but if you want to exec onto your Ubuntu container running in production and run VSCode quickly and easily, good luck with all that. (Admittedly, VSCode is a tool I do use occasionally, as it’s very powerful for certain use cases, very widely used, and seems designed to make engineers’ lives easier rather than collect a fee. But I do so under duress, usually.)

And because they use also typically use standard *nix conventions, these tools can be chained together to produce more and more bespoke solutions quickly and flexibly.

Users’ Needs Are Emphasised

LTD tools are generally written by and for the user’s needs, rather than any purchaser’s needs. Purchasers like fancy GUIs and point-and-click interfaces, and ‘new’ tools. Prettiness and novelty don’t help the user in the long term.

More Sustainable

These tools have been around for decades (in most cases), and are highly unlikely to go away. Once you’ve picked one for a task, it’s unlikely you’ll need a new one.

More Maintainable

Again, because these tools have been around for a long time, they tend to have a very stable interface and feature set. There’s little more annoying than picking up an old project and discovering you have to upgrade a bunch of dependencies and even rewrite code to get your project fired up again (I’m looking at you, node).

https://twitter.com/ciw1973/status/1525792853682790401

How We Use LTD

Here’s an edited example of a project I wrote for myself which mirrors some of the projects we have built for our more engineering-focussed clients.

Developer experience starts with a Makefile. Traditionally, Makefiles were used for compiling binaries efficiently and accounting for dependencies that may or may not need updating.

In the ‘modern’ world of software delivery, they can be used to provide a useful interface for the engineer for what the project can do. As the team works on the project they can add commands to the list for tasks that they often perform.

help:
@grep -E '^[a-zA-Z_-]+:.*?## .*$$' $(MAKEFILE_LIST) | sort | awk 'BEGIN {FS = ":.*?## "}; {printf "\033[36m%-30s\033[0m %s\n", $$1, $$2}'

docker_build: ## Build the docker image to run in
docker build -t data-scraper . | tee /tmp/data-scraper-docker-build
docker tag data-scraper:latest docker.io/imiell/data-scraper

get_latest: docker_build ## Get latest data
@docker run \
-w="/data-scraper" \
--user="$(shell id -u):$(shell id -g)" \
--volume="$(PWD):/data-scraper" \
--volume="$(HOME)/.local:/home/imiell/.local" \
-- volume="$(HOME)/.bash_history:/home/imiell/.bash_history" \
--volume="/etc/group:/etc/group:ro" \
--volume="/etc/passwd:/etc/passwd:ro" \
--volume="/etc/shadow:/etc/shadow:ro" \
--network="host" \
--name=get_latest_priority \
data-scraper \
./src/get-latest.sh

It’s a great way of sharing ‘best practice’ within a team.

I then have a make.sh script which wraps calls to make with features such as capturing logs in a standard format and cleaning up any left-over files once a task is done. I then use that script in a crontab in production like this:

*/5 * * * * imiell run-one /home/imiell/git/data-scraper/src/make.sh \
get_latest

Using run-one and cron I can effectively have a daemon running on my server with very little overhead.


If you like this, you might like one of my books:
Learn Bash the Hard Way

Learn Git the Hard Way
Learn Terraform the Hard Way

LearnGitBashandTerraformtheHardWay
Buy in a bundle here

A challenge with make is that it has quite a steep learning curve for most engineers to write, and an idiosyncratic syntax (to younger eyes, at least).

However, while it can seem tricky to write Makefiles, it’s relatively easy to use them, which makes them quite a useful tool for getting new team members onboarded quickly. And for my personal projects – given enough time passing – new team members can mean me! If I return to a project after a time, I just run make help and I can see instantly what my developer workflow looked like.

Here’s an example make help on a project I’m working on:

This means if I have to onboard a new engineer, they can just run make help to determine what actions they can perform, and because most of the tasks run in containers or use standard tooling, it should work anywhere the command line and Docker is available.

This idea is similar to Dagger, which seeks to be a portable CI/CD engine where steps run in containers. However, running Dagger on Kubernetes requires privileged access and carries with it a Dagger engine, which requires installation and maintenance. make requires none of these moving parts, which makes maintenance and installation significantly simpler. The primitives used in Make can be used in your CI/CD tool of choice to create a similar effect.

What Low-Tech Devex Tools Should You Know About?

Here is a highly opinionated list of LTD tooling that you should know:

shell

Mastery of shells are essential to LTD; they underpin almost all of them.

vim/emacs

Already mentioned above, vim is available everywhere and is very powerful and flexible. Other similar editors are available and inspire similar levels of religious fervour.

make

Make is the cockroach of build tools: it just won’t die. Others have come and gone, some are still here, but make is always there, does the job, and can’t go out of fashion because it’s always been out of fashion.

However, as noted above, the learning curve is rather steep. It also has its limits in terms of whizz-bang features.

Docker

The trendiest of these. I could talk instead of chroot jails and how they can improve devex and delivery a lot on their own, but I won’t go there, as Docker is now relatively ubiquitous and mature. Docker is best enjoyed as a command line interface (CLI) tool, and it’s speed and flexibility composed with some makefiles or shell scripts can improve developer experience enormously.

tmux / screen

When your annoying neighbour bangs on about how the terminal can’t give you the multi-window joy of a GUI IDE, crack your knuckles and show them one of these tools. Not only can they give you windowing capabilities, they can be manipulated faster than someone can move a mouse.

I adore tmux and key sequences like :movew -r and CTRL+B z CTRL+B SPACE are second nature to me now.

git

Distributed source control at the command line. ’nuff said.

curl

cURL is one of my favs. I prefer to use it over GUI tools like Postman, as you can just save command lines in Markdown files for how-to guides and playbooks. And it’s super useful when you want to debug a network request by ‘exporting as cURL command’ from Chrome devtools.

cloud shell

Cloud providers provide in-browser terminals with the provider’s CLI installed. This avoids the need to configure keys (if you are already logged in) and worry about the versioning or dependencies of the CLI. I agree with @hibri here.

https://twitter.com/hibri/status/1790320249826402678

ssh

Why bother with the faffs of remote desktops when you have ssh and tmux? If you depend on GUIs, that’s the problem you need to solve.

Finally, special mentions to these text user interfaces (TUIs) and dev-friendly tools:

  • k9s – text user interface (TUI) for Kubernetes
  • top/htop/ctop etc – monitoring tools
  • sar – monitoring/performance analysis tool
  • entr – run commands when specific files change. Get rapid feedback in dev.
  • nnn – file browser

If you like this, you might like one of my books:
Learn Bash the Hard Way

Learn Git the Hard Way
Learn Terraform the Hard Way

LearnGitBashandTerraformtheHardWay
Buy in a bundle here

This post was originally published here, and is re-posted with permission.

At 50 Years Old, Is SQL Becoming a Niche Skill?

This post was originally triggered – and I choose that word carefully – by a recent experience on a cloud cost-optimisation project. These experiences prompted me to consider how things had changed since I started working in software.

As part of the project that provoked me, I was researching the topic of cloud cost analysis and was struck by how many people complained that the tools the big three providers give you are not adequate to the task. I had a look myself and indeed found that the questions I wanted answering were difficult to answer using the GUI tools.

No problem, I thought: I’ll just download the raw CSVs and find an open source project that sticks the data in a database, allowing me to write whatever queries I want on the data. After some searching I couldn’t find any such project, so wrote one myself and stuck it on GitHub. Once this was built I could write all sorts of queries like ‘Compare costs per GCP service/project/sku with previous month, showing any percentage change greater than x’, modifying them at will to hone in on the specific data I was interested in much faster and more effectively than could be achieved with GUIs. Some of the more generic ones are in the repo.

While working on this with a very bright and knowledgeable younger colleague, I was struck by the fact that he’d never needed to learn SQL, and he made sense of these queries by comparing them to other JSON-based *QLs that he’d come across (PromQL, GraphQL etc). This surprised me.

The Good Old Days

I’m going to grossly simplify matters here, but when I was coming up in the industry (around 2001) three-tier backend applications were where it was at. There were webservers (usually Apache), application servers, and databases. Knowledge and experience was thin on the ground, so you had to know a bit of everything. HTML, Javascript (mostly form submission fiddling), a language to do business logic in the application server layer (usually Java in those days, but I’d sworn off it for life), and SQL for the database. Different people had different preferences and specialisms, but you had to have a basic knowledge of all those technologies to be an effective developer.

The entire development engineer industry was about ‘dev’ at this point. ‘Ops’ was a challenge that was at the time usually either done in a half-hearted way by the developers themselves (in smaller orgs), or passed over to the sysadmins to manage (in bigger orgs). The smaller orgs grew into a devops mindset (“we’re not hiring a separate team to support the operation of the system, it’s cheaper to get the devs to do it”), and the bigger ones embraced SRE (“we need capable engineers to support and manage site reliability engineer live systems and there’s economies of scale in centralising that.”). Data science was also not really a thing then.

There were DBAs but they were there to ensure backups were done, and punish those who polluted their treasured databases with poorly written queries or badly defined indexes. They therefore sometimes doubled up as SQL tutors to the devs. 

Since almost everyone was a dev, and devs did a bit of everything, engineers were often asked SQL questions in job interviews, usually starting with a simple join and then asking about indexes and performance characteristics for the more advanced candidate.

The Rise of the Specialist

Along with the rise of ops in the noughties came the continuation of increasing specialisation in the IT industry. We’d had the DBA for some time, but the ‘dev’ was gradually supplanted by the front-end engineer, the tester, the data scientist, the DevOps engineer, and later the SRE, the security engineer… the list goes on.

I say this was a continuation because this process has been going on since computers existed, from the original physicists and technicians that maintained and programmed machines the size of rooms bifurcating into COBOL and FORTRAN programmers in the 60s and 70s, leading to system admins in the 80s, and then network admins, and so on.

Parallels to this can be seen in the medical profession. Once upon a time we had a ‘ship’s surgeon‘, who had to deal with pretty much any ailment you might expect from having cannon balls fired at you while lugging your heavy cannons to face the enemy, and (in more peaceful moments) disease-ridden sailors sharing whatever diseased they’d brought in from shore leave. Fast-forward hundreds of years and we now have plastic surgeons that specialise in just in ear surgery (otologists).

And a similar thing seems to be happening with computing jobs. Whereas once upon a time everyone who interacted with a computer at work would have likely had to type in (or even write) a few SQL queries in the past, now there’s a data scientist for that. The dev now attends scrum meetings and complains about JIRA (and doesn’t even write much JQL).

Is SQL Becoming a Niche Skill?

So back to the issue at hand. Opinion seems to be divided on the subject. These interactions were typical when I asked on Twitter:

Screenshot 2024-05-02 at 12.47.05

There’s no doubt that historical demand for SQL has always been strong. While SQL’s elder sibling COBOL clings to life on the mainframe, SQL remains one of the most in-demand skills in the industry, according to the TIOBE index. In the 20 years since 2004 it’s gone from 7th to 8th most popular language along side mainstays like C and upstarts like C++, Java, and Visual Basic.

Not only that, but SQL is still a widely used data querying language outside its common domains. Those who prefer SQL to JQ (and who among us without a PhD in mathematics do not?) might be interested in DuckDB, a SQL-fronted alternative to jq. And facebook’s osquery, which gives a common SQL interface to query different operating systems’ state for compliance, security, or performance purposes.

‘Schemas Are Bad, M’Kay?’

In another recent project with a similar demographic of engineer, I was horrified to be voted down about using a relational database as the consensus was ‘schemas are bad’ and ‘MongoDB is more flexible’. This, I thought, is a world gone topsy-turvy. To gain dominion over your data, you need to wrestle it to the floor with a schema. Without that, you won’t have the power to range over it with whatever questions you have to ask it, and you won’t have a database, just a set of documents or a fancier filesystem.

To this it’s often objected that schemas are ‘hard to change’, but this is only true when you’ve got many users and code dependencies on the database or huge amounts of data, not when you’re initially building up a system. They can be annoying to change, because the syntax varies between vendor and you often end up looking up whether it’s ALTER TABLE ADD INDEX or CREATE INDEX. LLMs almost banish this problem, however, as they are incredibly good at saving you time on this.

Poking my head out of that world I’ve been shocked at how few people currently in IT really understand data programming/management these days. npm and Javascript sure, python probably, but data, its management and any programming around it seems to have been pushed to the sides for the ‘data scientists’ to deal with, as though data were not an essential aspect of pretty much any computing work.

But perhaps I’m just an old ship’s surgeon who might know how to saw a leg off and administer smelling salts, but doesn’t have the deft skill of an otologist who practices on their specialism on the daily. I’ll just call myself a ‘full stack’ engineer and hope no-one notices.


If you like this, you might like one of my books:
Learn Bash the Hard Way

Learn Git the Hard Way
Learn Terraform the Hard Way

LearnGitBashandTerraformtheHardWay
Buy in a bundle here

This post was originally published here, and is re-posted with permission.